

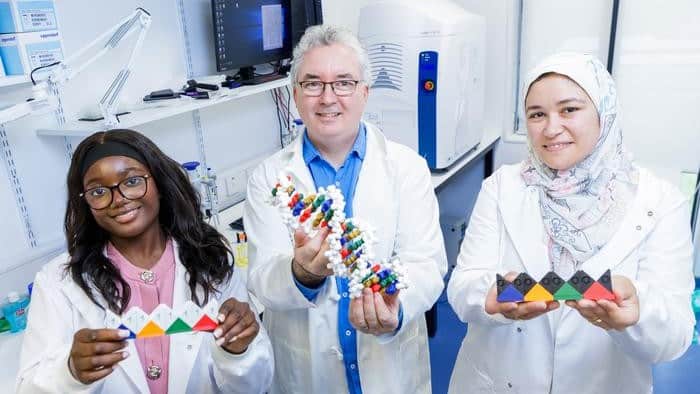
A DNA computer that calculates as it settles into thermal equilibrium has been unveiled in Ireland. Drawing together several earlier lines of research, Damien Woods and colleagues at Maynooth University created a DNA-based system that ran calculations far more quickly than they expected, and which could be easily implemented and reused with a relatively simple setup.
Much like a living organism, a computer runs far from thermal equilibrium. It expends energy to maintain encoded bits of information, and to switch between them quickly and reliably as it executes algorithms.
However, in the 1970s physicist Charles Bennett showed that any computation can, in principle, be modified to have reversible dynamics. Such a computer could operate close to thermal equilibrium, slashing its demand for energy.
Taking Bennett’s ideas a step further, others suggested that the output of an algorithm could be delivered in a system’s equilibrium state itself. Starting from a given set of inputs, the computer would then naturally drift towards the solution as it settles into its most stable state.
Multiple challenges
“The idea presents multiple challenges that include finding a physical implementation that is computationally expressive and programmable, has easily prepared initial states and has a controllable energy landscape for rapid navigation to target outputs with high probability,” Woods explains.
One promising platform is the DNA computer, which was first introduced in the 1990s. It replaces silicon chips and electrical currents with DNA strands and biochemical reactions.
Until now, much of the work on DNA computers has involved out-of-equilibrium systems, which are either driven by molecular fuel, or require carefully prepared initial states and tightly controlled experimental conditions. But because DNA strands bind to each other according to simple, predictable rules, researchers could engineer the energy landscape directly. Incorrectly bound strands would then detach and be replaced by better-fitting ones, until the system settles into its most stable state.
To build such a system, Woods’ team was inspired by “DNA origami”. In a 2006, US-based Paul Rothemund showed how a long, single-stranded DNA scaffold could bind to a chosen set of shorter strands. Depending on the strands chosen, the scaffold could fold into a wide array of shapes as it settled into thermal equilibrium.
Tile calculations
Applying these ideas to DNA computing, Woods’ team designed a DNA scaffold carrying an engineered sequence of binding domains, which they mixed into a solution of shorter DNA strands. Dubbed tiles by the researchers, these strands represent the possible values at each step of a calculation.
After mixing, the tiles compete with each other to bind to the scaffold, a form of molecular competition first devised by US-based Erik Winfree in the 1990s. At each binding domain, the “winning” tile is the one that binds most favourably to both the scaffold and its neighbouring tiles. In this way, the role of bits in a conventional computer is played by the specific strands that win each position.
“Eventually, the system settles down into its energetically preferred state which encodes the answer to the computation: a sequence of tiles each bound to the scaffold and to neighbouring tiles on its left and right,” Woods describes. “The competitive process of binding executes the computation.”
Altogether, the team demonstrated 10 different programs with their DNA computer, across more than 700 individual computations: including addition, multiplication, and division. Simple computations took as little as a minute to complete, though larger ones took considerably longer.
Just add water
“The same molecular computer can be reused to perform new calculations, running the same program up to 25 times on different inputs,” explains Maynooth’s Abeer Eshra. In one case, the team repeated an experiment after 15 months, simply adding water to a setup that had partially dried out, and still obtained correct answers.
Protocells help make DNA computer
“Our system uses just a handful of different kinds of molecules, never really following an organized process of steps, never making irreversible steps, and yet ending up with the right answer,” adds Maynooth’s Constantine Evans. “When thinking about computation at a molecular level, reliably making even those seemingly simple computations is very hard.”
The programs turned out to be surprisingly fast and easy to implement. To run a computation, the researchers simply mixed all the strands together, heated the solution, and let it cool as the system settled towards equilibrium, without any need for molecular fuel or specially prepared initial states. Remarkably, the team created what is arguably one of the most complex DNA computers built to date, paving the way for a whole host of new directions.
“Although we optimized some aspects of the design, there remain many ways it could be improved and generalized,” Woods says. “The work opens the door to new ways of thinking about computation in a wet environment, and about energy use in computation overall.”
The computer is described in Nature.